 how-to
How to Verify Browser File Processing in 2026
Table of Contents
- Why Verifying Browser File Processing Matters for Privacy
- Method 1: Use the Browser Developer Tools Network Tab
- Method 2: How to Check Network Requests With Offline Testing
- Method 3: Client-Side vs Server-Side Processing Explained
- Method 4: Verify File Integrity With Checksums
- Common Mistakes to Avoid When Verifying Processing
- Conclusion: Confirm Your Files Stay in the Browser
- Frequently Asked Questions
Last Updated: September 8, 2026
Why Verifying Browser File Processing Matters for Privacy
A growing number of web tools claim to process files locally, meaning your documents never leave your device. Yet the KeepAware State of Browser Security Report 2026 found that 23% of sensitive AI prompt uploads were verified as being sent through personal accounts, exposing a major blind spot in how users handle data in browser-based applications. Browser file processing is the practice of handling documents, images, or other data entirely within your browser's runtime environment rather than on a remote server.
At Inkwell Tools, we build privacy-respecting utilities that process core editing directly in your browser, so verifying this behavior is central to how we work. The stakes are straightforward: if a tool claims local processing but silently uploads your files, your confidential contracts, financial records, or client data could be exposed. Below, we'll show you exactly how to confirm that your files stay put, using four practical methods you can apply today.
Most guides assume you should trust a privacy policy at face value. The more reliable approach is technical verification, checking the actual network traffic your browser generates. Chrome holds 65.1% of the global browser market share according to Digital Applied's 2026 market report, which means these verification techniques apply to the majority of users immediately.
Method 1: Use the Browser Developer Tools Network Tab
The Network tab in browser developer tools is your first line of defense for verifying browser file processing. This panel records every HTTP request your browser makes, revealing whether data is transmitted to external servers during file handling. However, to truly verify processing, you must go beyond a simple request log and understand how the browser's process architecture relates to what you see on the network timeline.
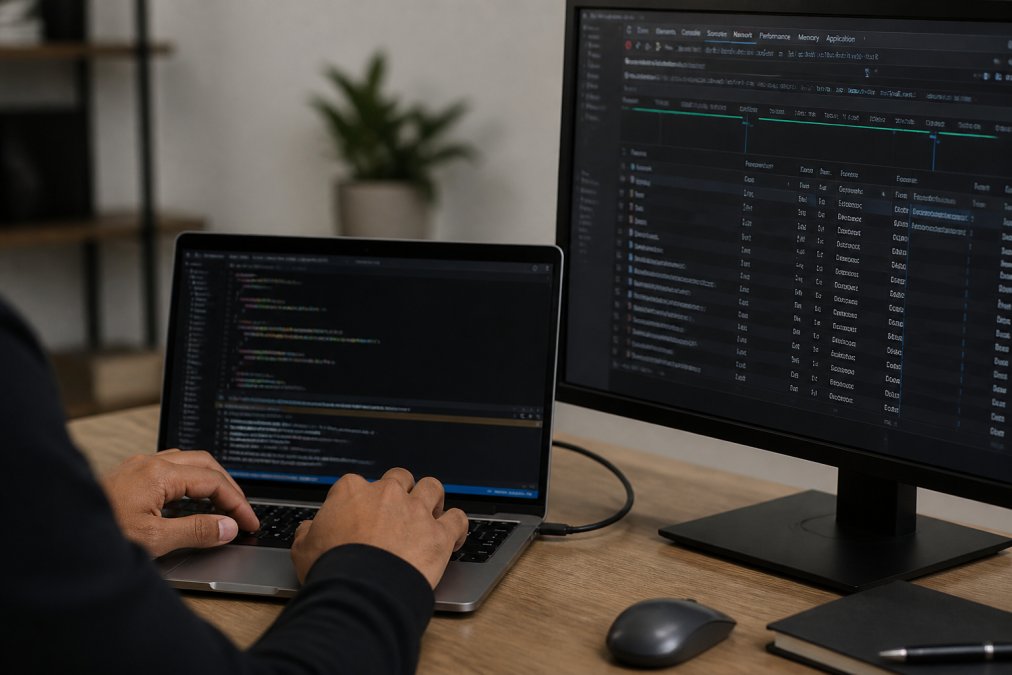
Open DevTools with F12 or Ctrl+Shift+I (Windows) or Cmd+Opt+I (Mac), then click the Network tab. Follow these steps to establish a baseline and isolate file-processing activity:
- Clear the log with the clear button to establish a baseline.
- Load the web tool and drag your file into the processing area.
- Watch the network log for any outgoing requests to external domains.
- Filter by "Fetch/XHR" to isolate API calls from static assets.
- Inspect each request's domain against the tool's official domain.
A clean log showing zero requests to third-party servers indicates genuine local processing. Any request to an unfamiliar domain, especially one with a different root URL, signals that your file data may be leaving the browser. This technique also helps you identify child processes spawned by the parent application that might handle data separately.
Going Deeper: Correlating Network Activity with Process Behavior
Competitors often stop at the network log, but a robust verification requires correlating that data with the browser's internal process model. Modern browsers like Chrome and Edge use a multi-process architecture where the main browser process, GPU process, and network service process each handle distinct tasks. When a web application processes a file locally, it typically does so within a renderer process. If the application spawns a dedicated service worker or a child process for file handling, you can observe this in the browser's built-in Task Manager.
To open Chrome's Task Manager, press Shift+Esc or navigate to Menu > More Tools > Task Manager. You will see a list of processes with columns for memory, CPU, and network usage. The key column is "Network," which shows real-time bytes sent and received for each process. During file processing, watch the renderer process associated with your active tab. If its network usage spikes from zero to several megabytes while you are dragging a file, that is direct evidence of an upload. Conversely, if the network column remains static while the CPU column spikes, the file is being processed locally.
For a more granular view, use the chrome://process-internals page (Chrome) or edge://process-internals (Edge). This page lists every active process, its type (e.g., renderer, utility, GPU), and the sites it is responsible for. You can match the process ID from this page to the one in the Task Manager to confirm which site is handling your file. A utility process dedicated to a specific site might indicate a sandboxed file parser, which is a good sign for local processing.
Filtering Out Noise: Extensions and Background Traffic
A common pitfall is mistaking extension traffic for application traffic. Extensions run in their own processes and can generate requests to their own servers. To isolate the web tool's activity, use the Network tab's filter bar to type domain:tool-domain.com (replace with the actual domain). This filters the log to only requests originating from or destined to that domain. Alternatively, open a new incognito window with extensions disabled (via chrome://extensions or the equivalent) to ensure a clean environment.
A Practical Example: Verifying a Local PDF Editor
Consider a web-based PDF editor that claims to process files locally. After loading the tool, open the Task Manager and note the network usage for the tab's renderer process. Drag a 10 MB PDF into the editor. If the tool is genuinely local, the network column will remain at 0 bytes, while the CPU column will spike as the JavaScript engine parses the PDF. If the tool uploads the file, you will see the network column climb to roughly 10 MB (plus protocol overhead) within seconds. Simultaneously, the Network tab will show a POST request to an API endpoint. This dual-check method, process-level network monitoring plus request-level inspection, eliminates false negatives where a tool might use a WebSocket or a less obvious request type.
By combining the Network tab with the browser's process manager, you move beyond simple observation and gain a forensic-level understanding of where your data travels. This method is the first step in a comprehensive verification workflow, and it directly supports the checksum and offline testing methods covered later in this guide.
Method 2: How to Check Network Requests With Offline Testing
Offline testing is the most conclusive way to check network requests and confirm local processing. If a tool continues functioning after you disconnect from the internet, the processing must be happening entirely in your browser environment.
The procedure takes about five minutes:
- Load the web tool in your browser and let it fully initialize
- Disable your Wi-Fi connection or unplug your Ethernet cable
- Attempt to process your file normally
- Observe whether the tool completes the operation without error
- Reconnect and compare the output with an online run
Tools that genuinely process locally will handle files identically offline. Tools that depend on server-side processing will fail, hang, or display connection errors. This method, recommended in PlatoForms' January 2026 security guidance, is particularly effective because it eliminates ambiguity entirely.
The limitation of offline testing is that some legitimate tools require initial asset loading from a CDN. If the tool fails immediately, verify whether the failure occurs before or after the file is selected, since asset loading should happen once at startup rather than during file processing.
Method 3: Client-Side vs Server-Side Processing Explained
Client-side processing runs entirely within your browser using JavaScript, while server-side processing transmits your file to a remote machine for handling. This distinction between client-side vs server-side processing determines where your data travels and who can access it.
Client-side tools use the JavaScript File API to read binary data as blob objects, process it locally, and generate output without a network request. Server-side tools, by contrast, send your file through a content-type header in an upload request, process it on their infrastructure, and return the result. The difference is visible in the Network tab: client-side processing generates no upload requests, while server-side processing always does.
| Processing Type | Network Activity | Data Exposure | Best For |
|---|---|---|---|
| Client-side | No upload requests | Minimal | Sensitive documents |
| Server-side | Upload request sent | Higher | Large files, complex operations |
Server-side processing is not inherently insecure, but it shifts trust to the service provider's security posture. When handling confidential files, client-side processing eliminates the transmission risk entirely. This is why privacy-focused tools, including those from Inkwell Tools, favor browser-based processing for sensitive operations like document conversion and editing.
Method 4: Verify File Integrity With Checksums
Beyond confirming where processing happens, you should verify that the output file matches your input exactly. Client-side checksum validation compares a hash of the original file against a hash of the processed result to detect any corruption or unauthorized modification.
Checksum validation is a hash validation technique that generates a unique fingerprint for each file. Any change to the file, even a single bit, produces a completely different hash. To verify file integrity:
- Calculate the SHA-256 hash of your original file using a command-line tool
- Process the file through the browser tool
- Calculate the SHA-256 hash of the output file
- Compare both hashes to confirm they match
On Windows, use certutil -hashfile yourfile.pdf SHA256. On macOS and Linux, use shasum -a 256 yourfile.pdf. Matching hashes confirm the tool preserved your data exactly, while mismatched hashes indicate corruption or unintended modification during processing.
Browser forensics research from Springer's 2025 evaluation of browser artifacts demonstrates that browser cache and history management leave traces of these operations. Understanding how to verify file integrity through checksums gives you a defense against both accidental corruption and malicious tampering, particularly when using web applications for sensitive document handling.
Common Mistakes to Avoid When Verifying Processing
The most common mistake when verifying browser file processing is checking the Network tab only during the initial page load rather than during actual file processing. Asset requests at startup are normal; the critical window is the moment you select and process a file.
A second frequent error is confusing browser cache activity with network transmission. Cached resources are stored locally and do not represent data exfiltration. Look specifically for outgoing requests to external servers rather than assuming all network activity is suspicious.
Third, many users forget that browser extensions can generate their own network traffic. A privacy blocker or analytics extension may create requests unrelated to the tool you are testing. Disable extensions temporarily or filter the Network log by the tool's domain to isolate its activity. Research from Check Point Research's browser security analysis shows that browser-native primitives can be exploited in ways that bypass user trust in local processing, making thorough verification essential.
Conclusion: Confirm Your Files Stay in the Browser
Verifying browser file processing comes down to three checks: monitoring network traffic, testing offline functionality, and validating output integrity through checksums. Each method addresses a different failure mode, and together they give you confidence that sensitive documents remain under your control. Privacy claims deserve scrutiny, and these technical techniques provide the evidence to back them up.
Inkwell Tools builds privacy-respecting utilities with core editing processed entirely in your browser, so you never have to wonder where your data goes. Our lean, single-purpose tools include a real free tier with no trial timers, letting you verify our processing approach before committing. Explore tools →
Frequently Asked Questions
How can I tell if a website is processing my files locally in the browser?
Open the browser developer tools network tab and watch for outgoing requests while you process a file. If no network activity occurs during the action, the processing is happening client-side. A stronger test is to disconnect from the internet and try again. If the tool still works offline, your file never left the device.
Does browser-based file processing mean my data is secure?
Client-side processing eliminates the risk of data interception during upload, which is a major privacy advantage. However, browser-native primitives can still be exploited by malicious scripts, as Check Point Research demonstrated in 2026. Always verify the site uses HTTPS, review its privacy policy, and monitor the network tab to confirm no data is being transmitted.
What is the difference between client-side and server-side file processing?
Client-side processing uses JavaScript to handle files entirely within your browser, so your data never leaves your device. Server-side processing sends the file to a remote server for handling, which means your data travels over the network and is stored temporarily or permanently on that server. You can identify which method a tool uses by checking the network tab for upload requests.
How do I check if my browser is monitored while processing files?
Monitor the browser developer tools network tab for unexpected outbound connections. Look for requests to domains unrelated to the tool you are using. Also check the process tree in your operating system's task manager for suspicious child processes spawned by the browser, which could indicate script-driven activity beyond normal file handling.