 ultimate-guide
Visualizing SQL Execution Plans for Beginners
Table of Contents
- Why Visualizing SQL Execution Plans Matters
- How to Generate Your First Actual Execution Plan
- Reading the Graphical Execution Plan: Operators and Icons
- Identifying Table Scans vs Index Seeks for Better Tuning
- Spotting Performance Bottlenecks: Arrow Thickness and Warnings
- SQL Query Performance Tuning Best Practices for Beginners
- Best SQL Execution Plan Visualizer Tools to Try
- Conclusion: Your First Steps Toward Faster Queries
- Frequently Asked Questions
Last Updated: September 9, 2026
SQL execution plans are the database engine's step-by-step roadmap for running a query, showing exactly how it accesses tables, joins data, and filters rows. This guide from Inkwell Tools breaks down how to read these graphical plans, spot the operators that slow queries down, and start tuning your SQL with confidence.
Why Visualizing SQL Execution Plans Matters
A query plan is defined as a series of concrete steps to execute a query written in a declarative language, such as SQL, serving as the fundamental roadmap for database performance (EXTERNAL_LINK: An Exploratory Case Study of Query Plan Representations | arxiv.org) (arxiv.org). Without seeing this roadmap, you are guessing at why a query runs slowly. Most developers write a query, see it perform poorly, and randomly add indexes or rewrite joins hoping something works. Visualizing the plan removes that guesswork by showing you exactly which step consumes the most time and resources.
The shift toward graphical execution plan interfaces is well underway. Modern database tooling is moving away from raw text and JSON parsing toward integrated dashboard visualizations to reduce cognitive load (EXTERNAL_LINK: Greptime Blog on execution plan visualization | greptime.com) (greptime.com). Major database management tools like DBeaver and SQL Server Management Studio now include native tree-viewers for execution plans as a standard feature (EXTERNAL_LINK: DBeaver and Microsoft documentation | dbeaver.com) (dbeaver.com).
How to Generate Your First Actual Execution Plan
Generating an actual execution plan is straightforward in most modern database tools. In SQL Server Management Studio, you click the "Include Actual Execution Plan" button before running your query. In DBeaver, you press Ctrl+Shift+E or select the execution plan option from the query menu. PostgreSQL users run EXPLAIN ANALYZE to get the plan with actual execution statistics.
Estimated vs. Actual Execution Plans
An estimated execution plan is generated by the query optimizer without running the query, based on statistics and guesses about data distribution. An actual execution plan runs the query and records real row counts, actual execution times, and actual data flow. For beginners, always start with the actual execution plan, as it reveals discrepancies between predictions and reality.
Reading the Graphical Execution Plan: Operators and Icons
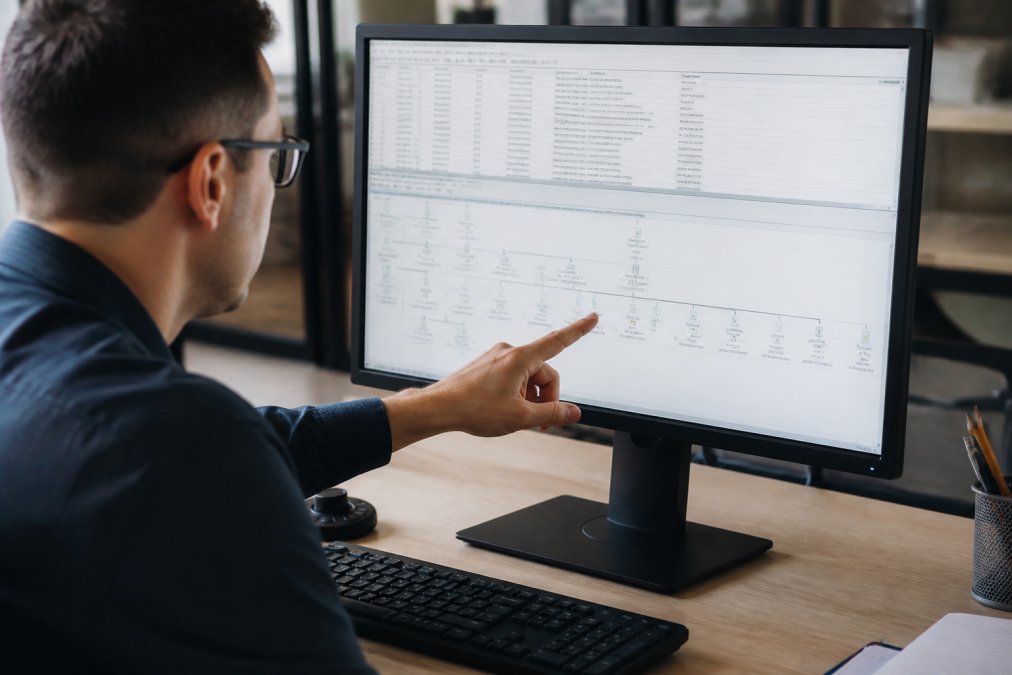
The graphical execution plan displays your query as a tree of icons flowing from right to left, with each icon representing a specific operation. Data flows from the right toward the left, where the final result is produced. Arrow thickness represents the volume of data moving between operations.
Logical vs. Physical Operators
SQL execution plans distinguish between logical and physical operators. Logical operators describe what the query needs to accomplish; physical operators describe how the engine accomplishes it, such as using a hash match or nested loops join. Beginners should focus on physical operators, as cost percentages next to each operator reveal where the query spends most of its time.
Identifying Table Scans vs Index Seeks for Better Tuning
In SQL Server Management Studio or DBeaver, a Table Scan icon looks like a table with an arrow sweeping across it, while an Index Seek icon shows a small index tree with a magnifying glass. These icons tell you exactly how the storage engine accessed your data.
What Each Operator Actually Does
A Table Scan reads every row in the heap or clustered index from the first page to the last. For a table with 10 million rows, that means 10 million row reads regardless of whether your WHERE clause matches one row or five. Its cost scales linearly with table size, often appearing as 50% or more of total query cost on large tables.
An Index Seek navigates the B-tree structure of an index to jump directly to rows matching your predicate. If you have an index on last_name and query WHERE last_name = 'Smith', the engine traverses the tree, finds the first match, and reads forward until the value changes. Rows read are proportional to matches, not table size.
An Index Scan (distinct from a Table Scan) reads every entry in the index. It is more efficient than a table scan because the index is narrower, but it still touches every row. You will see Index Scans when your query needs a large percentage of rows or when the index does not support a seekable predicate.
The query optimizer uses cost-based optimization, estimating I/O cost and picking the cheaper option. For a 500-row table, a scan might cost 0.003 seconds versus 0.008 for a seek due to tree traversal overhead, the scan is correct. The problem arises with a table scan on millions of rows, which almost always signals a missing index or a non-seekable predicate.
The Key Lookup Problem
The Key Lookup operator appears when the engine finds matching rows via a non-clustered index seek, but the query needs columns not included in that index. For each row found, the engine performs a separate lookup into the clustered index. If your query returns 10,000 rows, that is 10,000 additional random I/O operations, often more expensive than the original seek.
Real-World Example: The Missing Index Scenario
Consider SELECT order_id, order_total FROM orders WHERE customer_id = 4521 AND order_date > '2025-01-01'. With an index on customer_id only, the optimizer might seek on customer_id and filter order_date as a residual, or scan the entire index if too many rows match. The plan shows which path was chosen. If you see a scan or a seek followed by a filter with a high estimated-to-actual row mismatch, a composite index on (customer_id, order_date) will likely resolve it.
The plan's tooltip shows estimated and actual number of rows for each operator. When these diverge significantly, say, estimated 10 but actual 50,000, the optimizer made a cardinality misjudgment, often due to stale statistics. This mismatch is your cue to update statistics before rewriting any queries.
When a Scan Is the Right Choice
Do not assume every table scan is a problem. If 80% of rows match WHERE status = 'shipped', a scan is correct, seeking through an index for 80% of a table is slower than reading it all. The key skill is understanding the ratio of matched to total rows. When that ratio is low (under 5-10%) and you still see a scan, you likely have a missing index or a non-seekable predicate, such as WHERE YEAR(order_date) = 2025 instead of WHERE order_date >= '2025-01-01' AND order_date < '2026-01-01'.
Spotting Performance Bottlenecks: Arrow Thickness and Warnings
Arrow thickness and warning icons are your first visual cues, but knowing what to do when you see them separates a beginner from someone who can fix a slow query. This section provides a diagnostic flow to follow every time you spot a problem.
What Arrow Thickness Really Tells You
Arrow thickness represents the number of rows flowing between operators, a thin arrow might carry 5 rows, a thick one 500,000. Thick arrows typically appear when filtering happens too late. If you join two large tables and then apply a WHERE clause, the engine moves all matching rows through the join before discarding most. Moving the filter before the join reduces the row count through the expensive operator.
The Warning Icon Troubleshooting Checklist
When you see a yellow triangle warning icon on an operator, follow this step-by-step flow:
- Hover over the icon to read the warning text. The most common warnings are "CardinalityEstimateMismatch," "NoJoinPredicate," and "Convert" warnings.
- Check the estimated vs. actual rows in the tooltip. If estimated rows are 100 but actual rows are 10,000, the optimizer underestimated the data volume. This often leads to a nested loops join being chosen when a hash match would have been faster.
- Look at the statistics update date for the underlying table. Run
SELECT name, stats_date(object_id, stats_id) FROM sys.stats WHERE object_id = OBJECT_ID('your_table')in SQL Server to see when statistics were last updated. If they are older than the last significant data change, runUPDATE STATISTICS your_tableand re-run the query. - Check for implicit conversions. A "Convert" warning appears when you compare a column to a value of a different data type, such as comparing an
intcolumn to a string. The engine must convert every row, which prevents index seeks. Fix the query by using the correct data type in your parameter or literal. - Look for missing join predicates. A "NoJoinPredicate" warning means two tables are being cross-joined, producing a Cartesian product. This is almost always a bug in your query, you forgot the ON clause.
The Impact of Statistics on Plan Accuracy
Statistics are the data the optimizer uses to estimate row counts. SQL Server, PostgreSQL, and MySQL all maintain histogram data about column value distributions. When you insert, update, or delete a significant number of rows, those statistics become stale. A table that had 1,000 rows when statistics were last sampled might now have 2 million, but the optimizer still estimates based on the old distribution.
This is why a query might run fine for months and then suddenly degrade, the plan did not change, the data did. Warning icons are your early detection system. When you see a cardinality mismatch warning, check statistics freshness before rewriting the query or adding an index. Updating statistics is a low-effort fix that resolves a surprising percentage of slow queries.
A Real-World Diagnostic Walkthrough
Imagine a query joining customers and orders shows a thick arrow from a table scan on orders and a warning on a nested loops join. The tooltip shows estimated 50 rows, actual 150,000. Statistics were last updated six months ago, before a major data migration. You run UPDATE STATISTICS orders and re-run the query. The new plan shows an index seek on orders.customer_id and a hash match join, reducing query time from 12 seconds to 0.4 seconds, no index added, no query rewritten.
The execution plan is a diagnostic instrument that tells you which of three levers to pull: update statistics, add an index, or rewrite the query. Warning icons and arrow thickness tell you which applies, and the checklist ensures you do not skip the cheapest fix first.
SQL Query Performance Tuning Best Practices for Beginners
Start with the lowest-cost operation in the plan, since that is where the query spends the most time. Focus your tuning efforts there before looking elsewhere. A structured approach helps beginners avoid feeling overwhelmed by the complexity of execution plans, which are a huge topic that can be intimidating for those just starting out (EXTERNAL_LINK: Community discussion on execution plan complexity | reddit.com).
| Tuning Focus | What to Look For | Expected Impact |
|---|---|---|
| Table scans on large tables | Missing or unused indexes | Significant speedup |
| Thick arrows between operators | Filtering happening too late | Reduced data flow |
| Key lookups after index seeks | Covering index needed | Eliminates extra lookups |
| High-cost operators | Rewrite query or add index | Lower overall cost |
| Warning icons | Update statistics | Better plan choices |
One practitioner developed a three-line code function to generate visual representations of Spark execution plans for performance tuning, simplifying the transition from SQL-based tuning to Spark environments by providing immediate visual feedback (EXTERNAL_LINK: G. Brueckl's Spark plan visualization | gbrueckl.at). The same principle applies to SQL: seeing the plan makes the problem obvious.
Best SQL Execution Plan Visualizer Tools to Try
SQL Server Management Studio includes a built-in graphical execution plan viewer with color-coded operators and tooltips showing detailed cost information. DBeaver offers a similar tree-viewer that works across multiple database engines, including PostgreSQL and MySQL. Both tools allow you to save plans as files or images for documentation.
Each engine has its own optimizer quirks, and a plan that performs well in one database may fail in another. The execution plan cache and plan XML features let you examine historical plans. Inkwell Tools offers enterprise-grade database optimization tools that integrate plan analysis into a privacy-respecting workflow, with core processing handled in your browser so sensitive query data never leaves your machine.
Conclusion: Your First Steps Toward Faster Queries
Visualizing SQL execution plans turns an opaque performance problem into a clear set of actionable steps. Start by generating an actual execution plan for your slowest queries, identify the table scans and thick arrows that signal trouble, then address the bottlenecks the plan reveals.
Frequently Asked Questions
How do I view a SQL execution plan in my database environment?
In SQL Server Management Studio, highlight your query and press Ctrl+M to enable the actual execution plan, then execute. In PostgreSQL, run EXPLAIN ANALYZE before your query. MySQL uses EXPLAIN FORMAT=TREE. Most modern IDEs now include built-in tree viewers, making it easier to visualize SQL execution plans without parsing raw text.
What is the difference between an estimated and actual execution plan?
An estimated execution plan is generated by the query optimizer without running the query, based on statistics and cardinality estimation. An actual execution plan runs the query and shows real resource consumption, actual row counts, and warning icons. For performance tuning, actual plans are more accurate because they reveal discrepancies between estimated and actual rows.
Why is visualizing an execution plan better than reading raw text?
Visualizing SQL execution plans reduces cognitive load. Graphical interfaces show the flow of data from right to left, with arrow thickness representing row counts. This makes identifying table scans vs index seeks and other performance bottlenecks faster than reading plan XML. Tools like GreptimeDB have added dashboard visualizations because users understand complex execution paths at a glance.
How can I identify performance bottlenecks using execution plan visualization?
Look for warning icons (yellow or red) on operators, which indicate issues like missing statistics. Check for thick arrows, which signal large data transfers between operators. Heavy operators like table scans and key lookups are common bottlenecks. The plan highlights the costliest operator as a starting point for your query tuning.
What are the most common icons to look for in a SQL execution plan?
The most common icons represent physical operators: table scan, index scan, index seek, key lookup, nested loops, hash match, and merge join. Index seeks are generally efficient; table scans and index scans often indicate a missing or unused index. Key lookups suggest your index does not cover the query's columns.
What are common SQL execution plan anti-patterns for beginners?
A common anti-pattern is focusing only on the first operator you see. Plans read from right to left, and the most expensive operator is marked with a bold border. Another is ignoring the impact of statistics; stale statistics degrade plan accuracy. Also, avoid tuning queries in isolation without checking the execution plan cache for reuse.
Faster queries do not require guessing or luck. They require reading what the database is telling you through its execution plan. Inkwell Tools helps you act on that information with lean, single-purpose database optimization utilities that respect your privacy and process sensitive data in your browser. Explore the tools and start turning your slow queries into fast ones today.