Without indexes, the database performs a full table scan, reading every row to find matches. With indexes, it narrows the search space dramatically, reducing query latency and improving throughput.
Many teams add indexes reactively, only when queries slow down. Design them based on your actual workload from the start.
Step 2: Apply Database Indexing Best Practices
The fundamentals of database indexing strategies are straightforward. Apply these principles consistently:
Index selectivity matters. A column with many unique values is a better candidate than one with few; indexing a boolean column provides little benefit because the index still must scan many rows.
Monitor index usage. Unused indexes drain performance without benefit. Review your indexes regularly. Drop any index that queries never use.
Test before deploying. Create indexes on staging first, run your workload against it, and use EXPLAIN or EXPLAIN ANALYZE to confirm queries actually use the new indexes.
According to database performance optimization research, workload-specific index design outperforms generic approaches. Prioritize columns used by important queries while balancing read and write performance.
Step 3: Design Composite Index Examples for Your Workload
A composite index (or compound index) indexes multiple columns together, which is more powerful than single-column indexes for many queries.
Consider a query that filters on customer_id AND order_date:
SELECT * FROM orders
WHERE customer_id = 123 AND order_date > '2026-01-01'
A composite index on (customer_id, order_date) serves this query perfectly. The database uses the index to find all rows matching customer_id, then within those rows, filters by order_date.
Column order matters: put the most selective column first, then add columns that appear together in WHERE clauses.
Example: If most queries filter on customer_id first, then order_date, create the index as:
```sql
CREATE INDEX idx_customer_date ON orders(customer_id, order_date);
This index also helps queries that filter on customer_id alone. But it does NOT help queries that filter on order_date without customer_id. Column order determines which query patterns the index supports.
A **covering index** includes all columns a query needs, so the database never touches the main table. For this query:
```sql
SELECT customer_id, order_date, total
FROM orders
WHERE customer_id = 123
A covering index on (customer_id, total, order_date) lets the database satisfy the query entirely from the index, faster than jumping back to the main table.
<div style="margin:1.5rem 0; padding:16px 20px; background-color:#f0f9ff; border-left:4px solid #bae6fd; border-radius:0 8px 8px 0;">
<strong style="display:block; margin-bottom:4px; color:#111827; font-size:14px;"> Pro Tip</strong>
<span style="color:#374151; font-size:15px; line-height:1.6;">Composite indexes are more efficient than multiple single-column indexes. One composite index handles multiple query patterns. Multiple single-column indexes waste storage and slow writes.</span>
</div>
## Step 4: Analyze SQL Execution Plan Analysis to Measure Impact
Before and after you add an index, examine the **execution plan** to confirm the index is actually being used, the single most reliable way to prove an index change helped rather than hurt.
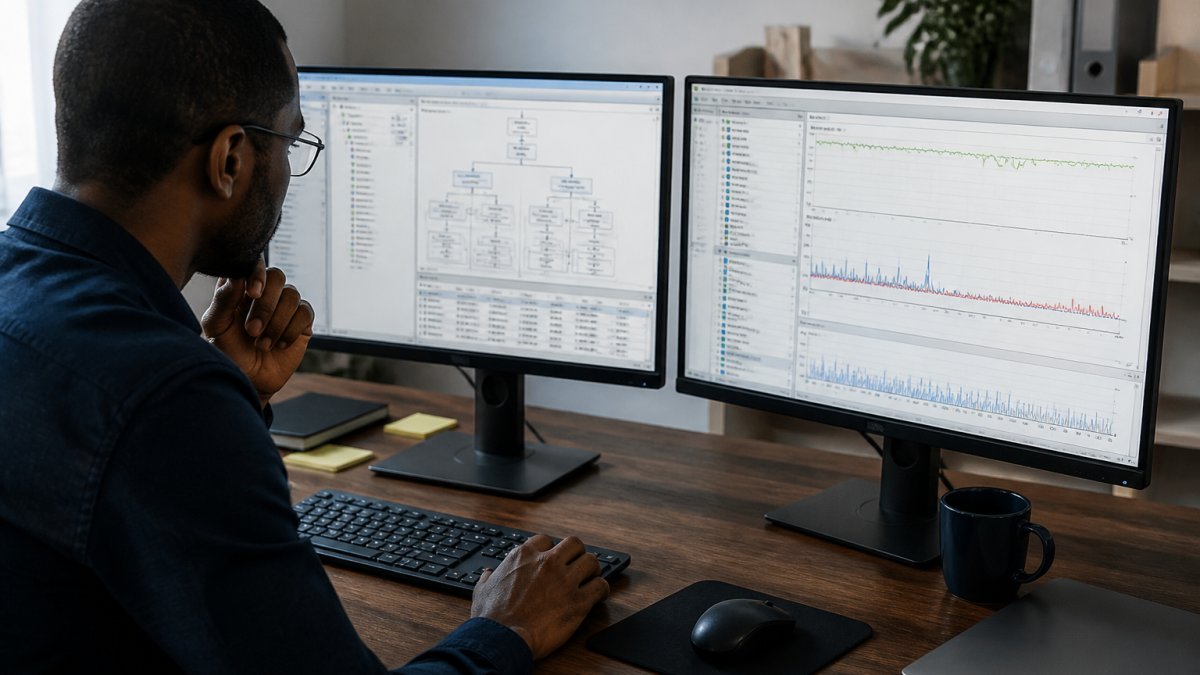
Database administrator reviewing performance metrics on a dual-monitor setup with one screen displaying query execution plans and performance graphs
### Read the plan, not just the query
An execution plan shows the access path the optimizer chose: indexes used, join order, estimated versus actual rows, and where time went. Key signals:
- **Index seek / index scan**: The database used your index to narrow results. A seek jumps directly to matching rows; a scan reads the index range. Both are usually better than a table scan.
- **Sequential scan / table scan / full scan**: The database read every row. On a large table this is the bottleneck you are trying to eliminate.
- **Estimated vs. actual rows**: A large gap between the optimizer's estimate and the real row count often means stale statistics, which can cause the optimizer to ignore a perfectly good index.
### Database-specific plan commands
The command and output format differ by system, so use the right one for your engine:
- **PostgreSQL**: `EXPLAIN (ANALYZE, BUFFERS) SELECT ...` runs the query and reports actual timing, row counts, and buffer usage. `ANALYZE` turns an estimate into measured reality; without it you only see the planner's guess.
- **MySQL**: `EXPLAIN SELECT ...` shows the access type per table (`const`, `ref`, `range`, `index`, `ALL`). `EXPLAIN ANALYZE` (MySQL 8.0.18+) adds actual execution timing. The `ALL` access type means a full table scan.
- **SQL Server**: Enable the actual execution plan in SQL Server Management Studio, or use `SET STATISTICS IO ON` and `SET STATISTICS TIME ON` to see logical reads and CPU time per statement. Logical reads are a strong proxy for how much work the query did.
### A repeatable before/after benchmark
Capture a baseline, make one change, and re-measure the same query under the same conditions.
1. **Capture the baseline.** Record the plan, actual elapsed time, and rows read for the slow query. On PostgreSQL, note `Buffers: shared hit=` and `read=`; on SQL Server, note logical reads from `STATISTICS IO`.
2. **Create one index.** Change a single variable so you can attribute the effect.
3. **Re-run the identical query.** Use the same parameters and data volume. Compare elapsed time, rows read, and the access path.
4. **Confirm the plan changed.** If the plan still shows a sequential scan, the index is not being used, check statistics, column order, and whether the query is sargable (for example, `WHERE YEAR(order_date) = 2026` prevents an index on `order_date` from being used, while `WHERE order_date >= '2026-01-01' AND order_date < '2027-01-01'` allows it).
5. **Record the result.** Keep the before/after numbers with the index definition so future reviewers understand why it exists.
Example: a query filtering `orders` by `customer_id` may show a sequential scan. After `CREATE INDEX idx_customer ON orders(customer_id);`, `EXPLAIN ANALYZE` should show an index scan and a sharp drop in rows read. If the row count is unchanged, the index is not doing its job.
<div style="margin:1.5rem 0; padding:16px 20px; background-color:#f0f9ff; border-left:4px solid #bae6fd; border-radius:0 8px 8px 0;">
<strong style="display:block; margin-bottom:4px; color:#111827; font-size:14px;"> Pro Tip</strong>
<span style="color:#374151; font-size:15px; line-height:1.6;">Measure with realistic data volumes. An index that looks great on a 10,000-row staging table may be ignored by the optimizer on a 10-million-row production table, because the planner weighs index cost against sequential scan cost differently at scale.</span>
</div>
Monitor **query latency** and **throughput** over time, not just once. Tools like Inkwell Tools provide execution plan visualization and query analysis to surface performance bottlenecks quickly. Track these metrics before and after indexing changes to prove the impact.
<div style="margin:1.5rem 0; padding:16px 20px; background-color:#f0fdf4; border-left:4px solid #bbf7d0; border-radius:0 8px 8px 0;">
<strong style="display:block; margin-bottom:4px; color:#111827; font-size:14px;"> Key Takeaway</strong>
<span style="color:#374151; font-size:15px; line-height:1.6;">Always verify index impact with execution plans and measured before/after numbers. A slow query after adding an index means the index is not being used, investigate statistics, column order, and sargability, or remove the index.</span>
</div>
## Step 5: Detect and Remove Unused Index Detection
Unused indexes consume storage, slow inserts and updates, and provide no query benefit.
Query your database system catalog to find unused indexes. In PostgreSQL:
```sql
SELECT schemaname, tablename, indexname, idx_scan
FROM pg_stat_user_indexes
WHERE idx_scan = 0;
Indexes with zero scans are candidates for deletion. In SQL Server, use:
```sql
SELECT * FROM sys.dm_db_index_usage_stats
WHERE database_id = DB_ID() AND user_updates > 0 AND user_seeks = 0;
This finds indexes that receive write traffic (updates) but zero read traffic (seeks), pure overhead.
Before dropping an unused index, confirm it is truly unused over a representative period, at least a week, to account for weekly or monthly patterns. Document why you are dropping it so no one recreates it later without understanding the decision.
<div style="margin:1.5rem 0; padding:16px 20px; background-color:#fffbeb; border-left:4px solid #fde68a; border-radius:0 8px 8px 0;">
<strong style="display:block; margin-bottom:4px; color:#111827; font-size:14px;"> Watch Out</strong>
<span style="color:#374151; font-size:15px; line-height:1.6;">Dropping an index can break application queries if your monitoring period was too short. Always test in staging first, and keep a backup of the drop statement in case you need to restore it.</span>
</div>
## Balancing Read Performance Against Write Overhead
Every index you add speeds some reads but slows all writes, and the right balance depends on the workload rather than a universal rule.
### Why writes get slower
Every insert, update, or delete must maintain each index on the table. Each index is a separate B-tree needing its own page splits, key insertions, and, for updates to indexed columns, delete-and-reinsert operations. A table with ten indexes pays that cost ten times per row change, and the effect compounds under concurrency as index maintenance takes locks and generates write-ahead log or redo traffic.
### A workload-based decision framework
Classify each table by read/write ratio and latency goals before deciding how many indexes it should carry.
- **OLTP (high write, point reads)**: Think order entry, session stores, event ingestion. Writes dominate, and each index adds latency to every transaction. Keep indexes minimal and targeted at the exact point-lookup and join patterns the application uses. Favor narrow indexes and avoid indexing columns that change frequently.
- **Analytics / reporting (read-heavy, large scans)**: Think dashboards and batch reports. Reads dominate and write overhead is less painful because loads are batched. Here, covering indexes and composite indexes that support GROUP BY and ORDER BY pay off, and you can afford more of them.
- **Mixed workloads**: The hardest case. Separate hot transactional tables from reporting tables where possible, or use read replicas so reporting indexes do not penalize the primary's write path. On a single table, index only the highest-value queries and accept that some ad hoc queries will scan.
For each table, ask: what percentage of operations are reads versus writes? How much query and write latency can you tolerate? Which queries are business-critical versus occasional? Do indexed columns change frequently or stay stable?
### Production-safe index changes
Changing indexes on a large, live table carries risk staging will not reveal. Plan the deployment:
- **Build indexes online where the engine supports it.** PostgreSQL supports `CREATE INDEX CONCURRENTLY`, which avoids blocking writes but takes longer and can fail partway, leaving an invalid index you must drop and retry. SQL Server Enterprise supports `ONLINE = ON` for many index operations. MySQL InnoDB supports online DDL for many index builds, but behavior varies by version and operation.
- **Sequence the change.** Create the new index first, verify the plan uses it, then drop the old one. Never drop before the replacement is confirmed in production.
- **Watch for locking and replication lag.** A large index build generates significant I/O and log traffic; schedule it for a low-traffic window and monitor replica delay.
### Review on a schedule
Index needs drift as query patterns and data volumes change. An index that made sense six months ago may be wasteful now, and a new feature may need one that did not exist before.
Start simple. Index only the columns that appear in your most important queries. Measure the impact. Add more indexes only if you have concrete evidence they help.
## Common Mistakes to Avoid When Optimizing Database Indexing Strategies
**Over-indexing** is the most common mistake.
**Ignoring write performance** is another trap. Developers focus on query speed and forget that indexes have a cost.
**Creating indexes without understanding the query** wastes effort.
**Assuming all databases work the same way** causes problems when you move between systems.
Developer Nation's database indexing optimization strategies recommends avoiding over-indexing and regularly monitoring and tuning indexes rather than adding them indiscriminately.
---
Optimizing **database indexing strategies** requires discipline. At Inkwell Tools, we help teams visualize [execution plans](https://blog.inkwelltools.com/visualizing-sql-execution-plans-for-beginners) and identify performance bottlenecks, so you can make index decisions based on data, not guesswork.
<section style="margin:3rem 0 2rem 0;" itemscope itemtype="https://schema.org/FAQPage"><h2 style="font-weight:700; margin:0 0 4px 0;">Frequently Asked Questions</h2><div style="padding:20px 0; border-bottom:1px solid #e5e7eb;" itemscope itemprop="mainEntity" itemtype="https://schema.org/Question"><h3 style="font-weight:600; margin:0 0 8px 0;" itemprop="name">How do I know which columns to index?</h3><div style="line-height:1.7;" itemscope itemprop="acceptedAnswer" itemtype="https://schema.org/Answer"><p itemprop="text" style="margin:0;">Start by analyzing your query workload. Identify columns that appear in WHERE clauses, JOIN conditions, and ORDER BY statements. Use EXPLAIN or EXPLAIN ANALYZE to see which columns are being filtered or sorted most frequently. Prioritize high-selectivity columns that filter out large portions of data. Monitor slow query logs to spot patterns. Avoid indexing low-cardinality columns (like boolean fields) unless they appear in composite indexes with higher-selectivity columns.</p></div></div><div style="padding:20px 0; border-bottom:1px solid #e5e7eb;" itemscope itemprop="mainEntity" itemtype="https://schema.org/Question"><h3 style="font-weight:600; margin:0 0 8px 0;" itemprop="name">Can too many indexes slow down a database?</h3><div style="line-height:1.7;" itemscope itemprop="acceptedAnswer" itemtype="https://schema.org/Answer"><p itemprop="text" style="margin:0;">Yes. Each index increases write overhead, inserts, updates, and deletes must update every relevant index. Over-indexing also wastes storage and complicates the query optimizer's decision-making. The database must maintain statistics on more indexes, and the planner may choose a suboptimal execution path. Monitor index usage regularly and remove redundant or unused indexes. Balance read gains against write costs by prioritizing indexes on heavily queried columns and removing those that don't measurably improve query performance.</p></div></div><div style="padding:20px 0; border-bottom:1px solid #e5e7eb;" itemscope itemprop="mainEntity" itemtype="https://schema.org/Question"><h3 style="font-weight:600; margin:0 0 8px 0;" itemprop="name">What is the difference between a clustered and nonclustered index?</h3><div style="line-height:1.7;" itemscope itemprop="acceptedAnswer" itemtype="https://schema.org/Answer"><p itemprop="text" style="margin:0;">A clustered index determines the physical order of rows in the table, each table has only one. Queries using the clustered index retrieve data directly without an extra lookup. A nonclustered index is a separate structure pointing to rows; lookups may require an additional step (called a bookmark lookup). Clustered indexes are ideal for range queries and sorting; nonclustered indexes work best for specific column lookups. Choose your clustered index carefully based on your most frequent query patterns.</p></div></div><div style="padding:20px 0; border-bottom:1px solid #e5e7eb;" itemscope itemprop="mainEntity" itemtype="https://schema.org/Question"><h3 style="font-weight:600; margin:0 0 8px 0;" itemprop="name">How often should database indexes be rebuilt or reorganized?</h3><div style="line-height:1.7;" itemscope itemprop="acceptedAnswer" itemtype="https://schema.org/Answer"><p itemprop="text" style="margin:0;">Rebuild indexes when fragmentation exceeds 30%; reorganize when it falls between 10-30%. Monitor fragmentation using dynamic management views or your database's built-in tools. Frequency depends on your write workload. High-transaction systems may need weekly maintenance; read-heavy systems may need it monthly or quarterly. Schedule rebuilds during off-peak hours to minimize impact on active queries. Monitor query performance and adjust your maintenance schedule based on observed degradation.</p></div></div></section>
 how-to